Can ChatGPT recommend your business? It ranks us #1.
Ask ChatGPT for the top YouTube video editing agencies in India and Shinel Studios comes first. Two weeks earlier, fifteen AI crawlers were being turned away at our door. Here is what we fixed — and the same playbook we now run for clients.
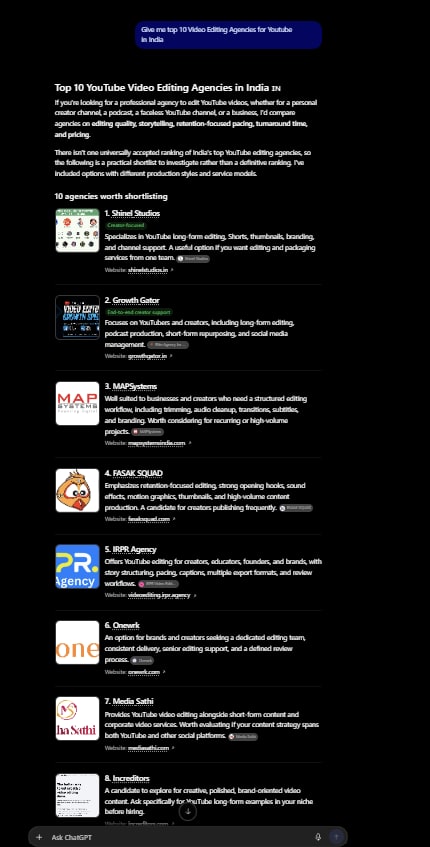
ChatGPT answer to “Give me top 10 Video Editing Agencies for Youtube in India”, 11 Oct 2026 — screenshot above. One prompt on one date; answers vary by user, session and model version
Cloudflare Security → Bot traffic, ai_bots_protection: block — GPTBot, ClaudeBot, CCBot, Bytespider, Meta-ExternalAgent, Amazonbot and others. Audited 2026-09-28, fixed the same week
Per-agent request for /, /llms.txt and /case-studies — GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, PerplexityBot, Googlebot. Re-run 2026-10-11
Line count of the live file at shinelstudios.in/llms.txt, 2026-10-09
What we think it means · The block was invisible because it was a policy, not a bug: one zone-level toggle 403'd a named list of crawlers while robots.txt kept saying they were welcome, and every human visitor saw a healthy site. Once the engines could read the pages, the rest was about being easy to quote — plain answers to the questions buyers actually ask, and a map (llms.txt) of where those answers live. That is the part that transfers: it is the same playbook we now run for creators and brands who want to be the name an assistant gives when someone asks for a recommendation in their niche.
Honest limits. AI answers are not a fixed ranking — the same prompt can return a different list for a different user, on a different day, or after a model update, so “#1” here means first in the answer we captured on 11 Oct 2026, nothing more. No assistant reports how often it cites a site, so anyone quoting you a precise AI citation count for a small brand is guessing — and we won't promise a position. What we can show is the before and after: engines that could not read the site, and now can. Figures read from the live portfolio on 11 October 2026; view counts move.
The brief.
More and more of the people who message us have already asked an assistant before they ever open a search box. They arrive knowing what we do and roughly what we charge — because ChatGPT, Perplexity or Gemini told them.
That channel has a different admission test from Google. Answer engines retrieve and synthesise from pages they can crawl, so a clear, well-structured, fully-readable site can be pulled into an answer without years of backlinks. Google gates more heavily on off-site authority, which is earned slowly.
Which makes one thing non-negotiable: the engines have to be able to read you. We assumed ours could, because robots.txt said so. A per-crawler test showed fifteen of them were being blocked — GPTBot included. Fixing that, and making the site easy to quote, is the work below.
What we did.
- Tested access per user-agent instead of reading robots.txt — one request per crawler, which is what actually surfaced the 403s
- Found the cause one layer below the file: a single Cloudflare bot setting, not a rule anyone had written
- Separated the two surfaces that get confused — robots.txt is a request, the bot layer is enforcement, and only one of them can return a status code
- Wrote llms.txt as a curated map of the site: 75 links, each with a line on what that page actually answers
- Made the per-agent check a build guard (npm run verify:ai) so a silent re-block announces itself instead of waiting to be noticed
More of the work.
The work behind this result
- Service
Web development
Fast, search-ready websites for creators and local businesses.
See websites - Free tool
Free channel audit
Score your channel in 60 seconds and get three fixes. No login.
Audit my channel - Service
AI-safe editing
Edits that stay clear of YouTube's AI-content and reused-content rules.
Stay monetized